36. The Design and Price of Information#
36.1. Overview#
Earlier lectures in this section asked which statistical experiment a decision maker should prefer.
Blackwell’s Theorem on Comparing Experiments gave the classic answer: experiment \(\mu\) is at least as informative as experiment \(\nu\) when every Bayesian decision maker attains weakly higher expected utility with \(\mu\).
This lecture asks a different question.
Suppose somebody owns the data and wants to sell it.
What should she sell, and at what price?
We study Bergemann et al. [2018], who analyze a monopolist data seller facing a buyer who already has some private information of his own.
The buyer’s private information is exactly what he would like to hide, because it determines his willingness to pay.
So the seller screens by offering a menu of statistical experiments, degrading the information sold to some buyers in order to charge more to others.
The central finding is that degrading information is not simply a matter of adding noise.
Blackwell’s order is a partial order, so two experiments can be ranked differently by different decision makers.
The seller exploits precisely those incomparable pairs: information has a vertical dimension, its quality, and a horizontal dimension, its position.
That horizontal dimension has no counterpart in ordinary monopoly screening over quality or quantity, and it is what allows the seller to extract rents that would otherwise be impossible to reach.
Along the way we will
compute the value of an arbitrary experiment to an arbitrary belief type,
verify numerically that Blackwell’s order fails to rank the experiments the seller wants to use,
solve the two-type screening problem by brute force and check it against the paper’s closed forms,
solve the continuum-of-types problem as a linear program, which reproduces the paper’s ironing and pooling results without any need to implement ironing by hand.
Let’s start with imports.
import matplotlib.pyplot as plt
import numpy as np
from scipy import stats
from scipy.optimize import linprog

plt.rcParams['figure.figsize'] = (10, 5)
np.set_printoptions(precision=4, suppress=True)
36.2. The decision problem#
A data buyer must choose an action \(a\) from a finite set \(A\) without knowing the state \(\omega\), which lives in a finite set \(\Omega\).
We work throughout with the matching case in which the buyer wants his action to match the state,
so that matching state \(\omega_i\) pays \(u_i > 0\) and any mismatch pays zero.
From here on we take two states and two actions, \(\Omega = \{\omega_1, \omega_2\}\) and \(A = \{a_1, a_2\}\), which is the case Bergemann et al. [2018] solve completely.
The buyer’s type is his interim belief
which is private information.
The seller knows only the distribution \(F\) from which \(\theta\) is drawn.
Without extra information the buyer picks the better of two constant actions, so his reservation utility is
The type that is least sure what to do is the one where the two terms are equal,
Types above \(\theta^*\) would choose \(a_1\) on their own, types below would choose \(a_2\).
Note
The buyer’s belief \(\theta\) can be generated from a common prior together with a privately observed signal, exactly as in Likelihood Ratio Processes and Bayesian Learning and Exchangeability and Bayesian Updating.
A buyer with a very precise private signal has \(\theta\) near \(0\) or \(1\); a buyer who has learned nothing sits at the common prior, which equals \(\theta^*\) only by coincidence.
A “high type” in this lecture is a buyer whose belief lies near \(\theta^*\), and he is willing to pay the most.
When the common prior equals \(\theta^*\), high types are the badly informed buyers.
36.3. Experiments and their value#
A statistical experiment is a stochastic matrix mapping states into signals.
With two states and two actions it suffices to consider two signals, and we write
where row \(i\) gives the signal distribution in state \(\omega_i\).
Thus \(\pi_1 = \Pr[s_1 \mid \omega_1]\) and \(\pi_2 = \Pr[s_2 \mid \omega_2]\).
We adopt the normalization \(\pi_1 + \pi_2 \geq 1\), which just says that signal \(s_1\) is relatively more likely in state \(\omega_1\) than in state \(\omega_2\).
The fully informative experiment \(\overline{E}\) has \(\pi_1 = \pi_2 = 1\).
After seeing signal \(s_k\) the buyer picks the action with the highest expected payoff, so his gross value is obtained by summing the best he can do signal by signal.
Subtracting his reservation utility (36.2) gives the net value of information
def value(pi1, pi2, theta, u1=1.0, u2=1.0):
    """Net value of experiment (pi1, pi2) to a buyer with belief theta."""
    theta = np.asarray(theta, dtype=float)
    s1 = np.maximum(theta * pi1 * u1, (1 - theta) * (1 - pi2) * u2)
    s2 = np.maximum(theta * (1 - pi1) * u1, (1 - theta) * pi2 * u2)
    return s1 + s2 - np.maximum(theta * u1, (1 - theta) * u2)
If the buyer simply obeys the recommendation implicit in each signal, taking \(a_1\) after \(s_1\) and \(a_2\) after \(s_2\), the value collapses to
which is the expression the paper works with.
def value_obedient(pi1, pi2, theta, u1=1.0, u2=1.0):
    """Value when the buyer follows the recommendation, or ignores the signal."""
    theta = np.asarray(theta, dtype=float)
    return np.maximum(theta * pi1 * u1 + (1 - theta) * pi2 * u2
                      - np.maximum(theta * u1, (1 - theta) * u2), 0.0)
The two expressions agree exactly under the normalization \(\pi_1 + \pi_2 \geq 1\) and can differ sharply without it, which is what the normalization is for.
grid = np.linspace(0, 1, 2001)
worst_ok = worst_bad = 0.0
for p1 in np.linspace(0, 1, 51):
    for p2 in np.linspace(0, 1, 51):
        gap = np.abs(value(p1, p2, grid) - value_obedient(p1, p2, grid)).max()
        if p1 + p2 >= 1:
            worst_ok = max(worst_ok, gap)
        else:
            worst_bad = max(worst_bad, gap)

print(f'largest gap where pi1 + pi2 >= 1:  {worst_ok:.2e}')
print(f'largest gap where pi1 + pi2 <  1:  {worst_bad:.4f}')
largest gap where pi1 + pi2 >= 1:  1.11e-16
largest gap where pi1 + pi2 <  1:  0.5000
Under the normalization, reversing the recommendation, taking \(a_2\) after \(s_1\) and \(a_1\) after \(s_2\), is dominated by ignoring the signal, so every type either obeys or ignores.
That is why the two formulas coincide for every \(\theta\), including types who misreport and buy an experiment designed for somebody else.
We use the general form (36.5) from here on because it does not rely on the normalization.
Here is the value of information as a function of the buyer’s type.
theta = np.linspace(0, 1, 1001)

fig, axes = plt.subplots(1, 2, figsize=(11, 4))
for ax, (p1, p2), ttl in zip(
        axes, [(1.0, 1.0), (0.5, 1.0)],
        [r'fully informative $(\pi_1,\pi_2)=(1,1)$',
         r'partially informative $(\pi_1,\pi_2)=(1/2,1)$']):
    ax.plot(theta, value(p1, p2, theta), lw=2)
    ax.axvline(0.5, color='0.6', ls='--', lw=1)
    ax.set(xlabel=r'$\theta$', ylabel=r'$V(E,\theta)$', title=ttl)
fig.suptitle('Value of information, $u_1 = u_2 = 1$')
fig.tight_layout()
plt.show()

Fig. 36.1 Value of full and partial information#
Three features of these pictures drive everything that follows.
The value is piecewise linear in \(\theta\), because types are probabilities and expected utilities are linear in probabilities.
The value is highest at \(\theta^*\) and falls to zero at \(\theta \in \{0, 1\}\): the buyer who already knows the state will pay nothing, and the buyer who knows least will pay most.
The partially informative experiment in the right panel is worth nothing at all to types above \(2/3\), even though it is worth a great deal to types just below \(1/2\).
That last property is the seller’s main tool.
36.4. Blackwell’s order is only partial#
Blackwell’s Theorem on Comparing Experiments establishes that experiment \(E\) is at least as informative as \(E'\) in Blackwell’s sense exactly when \(E'\) is a garbling of \(E\).
In the notation of Definition 30.1, with \(\mu = E\) and \(\nu = E'\), there is a Markov matrix \(Q\) with
When \(E\) is invertible this is easy to check: solve \(Q = E^{-1}E'\) and ask whether every entry of \(Q\) is nonnegative.
The rows of \(Q\) sum to one automatically: \(E Q \mathbf{1} = E' \mathbf{1} = \mathbf{1} = E \mathbf{1}\), and \(E\) is invertible, so \(Q \mathbf{1} = \mathbf{1}\).
def experiment(pi1, pi2):
    return np.array([[pi1, 1 - pi1], [1 - pi2, pi2]])


def garbling(E, Ep, tol=1e-9):
    """Return Q with Ep = E @ Q if Ep is a garbling of E, else None."""
    if abs(np.linalg.det(E)) < tol:
        return None
    Q = np.linalg.solve(E, Ep)           # rows of Q sum to one automatically
    if (Q > -tol).all():
        return Q
    return None


pairs = [((1, 1), (0.8, 1)), ((1, 1), (1, 0.8)),
         ((0.9, 0.9), (0.8, 0.8)),
         ((0.8, 1), (1, 0.8)), ((1, 0.8), (0.8, 1))]
for a, b in pairs:
    ok = garbling(experiment(*a), experiment(*b)) is not None
    print(f'  is {b} a garbling of {a}?  {"yes" if ok else "no"}')
  is (0.8, 1) a garbling of (1, 1)?  yes
  is (1, 0.8) a garbling of (1, 1)?  yes
  is (0.8, 0.8) a garbling of (0.9, 0.9)?  yes
  is (1, 0.8) a garbling of (0.8, 1)?  no
  is (0.8, 1) a garbling of (1, 0.8)?  no
The fully informative experiment garbles into everything, and \((0.9, 0.9)\) garbles into the uniformly noisier \((0.8, 0.8)\).
Those are the vertical comparisons, and Blackwell’s theorem says every type agrees about them.
But \((0.8, 1)\) and \((1, 0.8)\) garble into each other in neither direction.
Blackwell’s order simply does not rank them, and that means different types are free to rank them differently.
va, vb = value(0.8, 1, theta), value(1, 0.8, theta)

fig, ax = plt.subplots()
ax.plot(theta, va, lw=2, label=r'$E_a = (0.8, 1)$')
ax.plot(theta, vb, lw=2, label=r'$E_b = (1, 0.8)$')
ax.fill_between(theta, va, vb, where=va > vb, alpha=0.15, color='C0')
ax.fill_between(theta, va, vb, where=vb > va, alpha=0.15, color='C1')
ax.axvline(0.5, color='0.4', ls='--', lw=1)
ax.set(xlabel=r'$\theta$', ylabel=r'$V(E,\theta)$',
       title='Types below $1/2$ prefer $E_a$, types above prefer $E_b$')
ax.legend()
fig.tight_layout()
plt.show()

for t in [0.2, 0.35, 0.65, 0.8]:
    pref = 'E_a' if value(0.8, 1, t) > value(1, 0.8, t) else 'E_b'
    print(f'  theta = {t}:  V(E_a) = {value(0.8, 1, t):.4f},'
          f'  V(E_b) = {value(1, 0.8, t):.4f}   prefers {pref}')

Fig. 36.2 Two experiments that Blackwell’s order does not rank#
  theta = 0.2:  V(E_a) = 0.1600,  V(E_b) = 0.0400   prefers E_a
  theta = 0.35:  V(E_a) = 0.2800,  V(E_b) = 0.2200   prefers E_a
  theta = 0.65:  V(E_a) = 0.2200,  V(E_b) = 0.2800   prefers E_b
  theta = 0.8:  V(E_a) = 0.0400,  V(E_b) = 0.1600   prefers E_b
Signal \(s_1\) of \(E_a\) occurs only in state \(\omega_1\), so it rules out \(\omega_2\); signal \(s_2\) of \(E_b\) occurs only in state \(\omega_2\), so it rules out \(\omega_1\).
A buyer who leans toward \(\omega_1\) takes \(a_1\) on his own and switches to \(a_2\) only on strong evidence for \(\omega_2\).
\(E_b\) supplies conclusive evidence for \(\omega_2\), so he values \(E_b\).
A buyer who leans toward \(\omega_2\) values \(E_a\) for the same reason.
This is the horizontal dimension of information.
In ordinary nonlinear pricing over quality or quantity, all types agree on the ranking of products and the seller can only move up and down a single ladder.
Here the seller has a second dial, and turning it lets her hand one type something that is worthless to another.
36.5. The seller’s problem#
The seller commits to a menu \(\{E(\theta), t(\theta)\}\) assigning an experiment and a price to each reported type.
Payments cannot be made contingent on the state, the signal, or the buyer’s action, so the value of an experiment to a buyer is determined by his belief alone.
Writing \(V(\theta) = V(E(\theta), \theta) - t(\theta)\) for the buyer’s rent, the seller solves
subject to incentive compatibility and individual rationality,
Bergemann et al. [2018] establish structural results that every menu we compute confirms.
Proposition 36.1
The fully informative experiment \(\overline{E}\) is part of an optimal menu.
Every experiment in any optimal menu is nondispersed, meaning \(\pi_{ij} = 0\) for some \(i \neq j\).
In the matching case every experiment in any optimal menu is concentrated, meaning \(\pi_{ii} = 1\) for some \(i\).
Part 3 says that in our binary setting every experiment on the menu has \(\pi_1 = 1\) or \(\pi_2 = 1\).
With two states and two signals, a zero off-diagonal entry forces a one on the diagonal of the same row, so “nondispersed” and “concentrated” coincide.
An optimal experiment keeps one signal that perfectly reveals one state; the other signal is noisy.
36.6. Two types#
Take two types \(\theta^L\) and \(\theta^H\), with \(\theta^H\) the high value type in the sense that he values the fully informative experiment more,
With \(u_1 = u_2\) this says \(|\theta^H - 1/2| \leq |\theta^L - 1/2|\), so the high type is the one who is less well informed to begin with.
Let \(\gamma = \Pr[\theta = \theta^H]\).
The types are congruent if \(\theta^* < \theta^H < \theta^L\), so both would take the same action without extra information, and noncongruent if \(\theta^L < \theta^* < \theta^H\).
An optimal menu has the familiar shape: the high type buys \(\overline{E}\), the low type’s participation constraint binds, and the high type’s incentive constraint binds.
Those three facts pin down both prices once the low type’s experiment is chosen.
To search over all low-type experiments we also need prices for experiments that the high type values less than the low type does.
For those, the price that makes the high type’s incentive constraint bind exceeds his value of \(\overline{E}\), so his participation constraint binds instead.
The function below charges the high type the smaller of the two prices.
def two_type_revenue(pi1, pi2, tL, tH, gamma, u1=1.0, u2=1.0):
    """Revenue when the high type buys E_bar and the low type buys (pi1, pi2)."""
    VbarH, VbarL = value(1, 1, tH, u1, u2), value(1, 1, tL, u1, u2)
    VL_L, VL_H = value(pi1, pi2, tL, u1, u2), value(pi1, pi2, tH, u1, u2)
    t_low = VL_L                                  # low type's IR binds
    t_high = min(VbarH - VL_H + t_low,            # high type's IC
                 VbarH)                           # high type's IR
    if VbarL - t_high > 1e-12:                    # low type must not deviate
        return -np.inf
    return gamma * t_high + (1 - gamma) * t_low
36.6.1. Noncongruent types#
Set \(\theta^L = 1/5\) and \(\theta^H = 7/10\) with \(u_1 = u_2 = 1\), so that \(\theta^* = 1/2\) lies between them.
Because the two types would take different actions on their own, the seller can build an experiment that is valuable to one and worthless to the other.
Choosing \(\pi_2 = 1\) and
leaves the high type exactly indifferent between his two actions after signal \(s_2\), so the experiment is worth nothing to him while the low type values it strictly.
That is feasible but not optimal.
The seller does better by making the high type’s incentive constraint bind instead, which gives
tL, tH, u1, u2 = 0.2, 0.7, 1.0, 1.0
pi1_zero = (u1 * tH - u2 * (1 - tH)) / (u1 * tH)
pi1_opt = (u1 * tH - u2 * (1 - tH)) / (u1 * (tH - tL))

print(f'zero-value-to-high experiment   pi1 = {pi1_zero:.4f}  (= 4/7)')
print(f'binding-IC experiment           pi1 = {pi1_opt:.4f}  (= 4/5)')
print(f'\n  V(E_zero, theta_H) = {value(pi1_zero, 1, tH):.4f}')
print(f'  V(E_opt,  theta_L) = {value(pi1_opt, 1, tL):.4f}'
      f'    V(E_opt, theta_H) = {value(pi1_opt, 1, tH):.4f}')
zero-value-to-high experiment   pi1 = 0.5714  (= 4/7)
binding-IC experiment           pi1 = 0.8000  (= 4/5)

  V(E_zero, theta_H) = 0.0000
  V(E_opt,  theta_L) = 0.1600    V(E_opt, theta_H) = 0.1600
The second experiment gives both types the same net value of information, \(0.16\).
The seller charges the low type \(0.16\) for it and charges the high type his full value of \(\overline{E}\).
The high type’s incentive constraint binds, and so do both participation constraints.
The seller extracts the entire surplus from both types; the only cost of screening is the distortion of the low type’s experiment.
fig, axes = plt.subplots(1, 2, figsize=(12, 4.2))
for ax, p1, ttl in zip(axes, [pi1_zero, pi1_opt],
                       ['suboptimal menu: partial experiment worth zero to $\\theta^H$',
                        'optimal menu: high type indifferent between the two items']):
    t_hi = value(1, 1, tH)                                     # price of E_bar
    t_lo = value(p1, 1, tL)                                    # price of partial item
    ax.plot(theta, value(1, 1, theta) - t_hi, lw=2, label='fully informative')
    ax.plot(theta, value(p1, 1, theta) - t_lo, lw=2, ls='--',
            label=f'partial, $\\pi_1={p1:.3f}$')
    ax.axhline(0, color='0.3', lw=1)
    for t, nm in [(tL, r'$\theta^L$'), (tH, r'$\theta^H$')]:
        ax.axvline(t, color='0.7', ls=':', lw=1)
        ax.annotate(nm, (t, ax.get_ylim()[0]), fontsize=9)
    ax.set(xlabel=r'$\theta$', ylabel=r'$V - t$', title=ttl, ylim=(-0.35, 0.25))
    ax.legend(fontsize=8, loc='upper left')
fig.tight_layout()
plt.show()

Fig. 36.3 Net value of the two menus as a function of the buyer’s type#
In the left panel the high type’s net value of the fully informative experiment lies strictly above his net value of the partial one, so his incentive constraint is slack and the seller is leaving money on the table.
In the right panel the two curves meet exactly at \(\theta^H\).
Now we check the closed form (36.11) against a brute-force search over all experiments.
def brute_force(tL, tH, gamma, n=301, u1=1.0, u2=1.0):
    """Search over all (pi1, pi2) for the best low-type experiment."""
    g = np.linspace(0, 1, n)
    best, arg = -np.inf, None
    for p1 in g:
        for p2 in g:
            if p1 + p2 < 1:
                continue
            r = two_type_revenue(p1, p2, tL, tH, gamma, u1, u2)
            if r > best:
                best, arg = r, (p1, p2)
    return best, arg


print(f'{"gamma":>7s}{"brute force":>13s}{"argmax":>18s}'
      f'{"closed form":>14s}{"E_bar to both":>15s}')
for gamma in [0.10, 0.25, 0.30, 0.50, 0.90]:
    best, arg = brute_force(tL, tH, gamma)
    closed = two_type_revenue(pi1_opt, 1.0, tL, tH, gamma)
    both = two_type_revenue(1.0, 1.0, tL, tH, gamma)
    print(f'{gamma:7.2f}{best:13.5f}   ({arg[0]:.3f}, {arg[1]:.3f})'
          f'{closed:14.5f}{both:15.5f}')
print(f'\nthe paper: discriminate iff gamma > theta_L / theta_H = {tL / tH:.4f}')
  gamma  brute force            argmax   closed form  E_bar to both
   0.10      0.20000   (1.000, 1.000)       0.17400        0.20000
   0.25      0.20000   (1.000, 1.000)       0.19500        0.20000
   0.30      0.20200   (0.800, 1.000)       0.20200        0.20000
   0.50      0.23000   (0.800, 1.000)       0.23000        0.20000
   0.90      0.28600   (0.800, 1.000)       0.28600        0.20000

the paper: discriminate iff gamma > theta_L / theta_H = 0.2857
The brute-force optimum sits at \((\pi_1, \pi_2) = (0.8, 1)\) whenever discrimination pays, matching (36.11) exactly, and at \((1, 1)\) otherwise.
The switch happens right at \(\gamma = \theta^L / \theta^H\).
When low types are common the seller prefers to sell everyone the fully informative experiment cheaply; when high types are common she prefers to protect the high price by degrading what the low type gets.
Note also that both experiments in the optimal menu have \(\pi_2 = 1\), confirming part 3 of Proposition 36.1.
36.7. A continuum of types#
Now let \(\theta\) be distributed on \([0,1]\) with density \(f\) and distribution \(F\).
The key simplification is that the value of a concentrated experiment depends on \((\pi_1, \pi_2)\) only through the scalar
which Bergemann et al. [2018] call the differential informativeness of the experiment.
By part 3 of Proposition 36.1, restricting the seller to concentrated experiments loses nothing.
For other experiments \(q\) does not determine the value: with \(u_1 = u_2 = 1\), the experiments \((0.8, 0.8)\), \((0.9, 0.9)\) and \((1, 1)\) all have \(q = 0\), but at \(\theta = 1/2\) they are worth \(0.3\), \(0.4\) and \(0.5\).
In terms of \(q\) the value becomes
The fully informative experiment is \(q = u_1 - u_2\).
The two endpoints \(q = -u_2\) and \(q = u_1\) are the experiments in which one signal occurs with probability one in both states, so they convey nothing.
def value_q(q, theta, u1=1.0, u2=1.0):
    """Value of the experiment with differential informativeness q."""
    theta = np.asarray(theta, dtype=float)
    gross = theta * q + u2 + np.minimum(u1 - u2 - q, 0.0)
    return np.maximum(gross - np.maximum(theta * u1, (1 - theta) * u2), 0.0)


def q_to_experiment(q, u1=1.0, u2=1.0):
    """Recover (pi1, pi2) from q using pi1 = 1 or pi2 = 1."""
    return (1.0, (u1 - q) / u2) if q >= u1 - u2 else ((q + u2) / u1, 1.0)


for q in [-1.0, -0.5, 0.0, 0.5, 1.0]:
    p1, p2 = q_to_experiment(q)
    print(f'  q = {q:+.2f}  ->  (pi1, pi2) = ({p1:.3f}, {p2:.3f}),'
          f'   max value over types = {value_q(q, theta).max():.4f}')
  q = -1.00  ->  (pi1, pi2) = (0.000, 1.000),   max value over types = 0.0000
  q = -0.50  ->  (pi1, pi2) = (0.500, 1.000),   max value over types = 0.2500
  q = +0.00  ->  (pi1, pi2) = (1.000, 1.000),   max value over types = 0.5000
  q = +0.50  ->  (pi1, pi2) = (1.000, 0.500),   max value over types = 0.2500
  q = +1.00  ->  (pi1, pi2) = (1.000, 0.000),   max value over types = 0.0000
A menu is now a function \(q(\theta)\), and incentive compatibility requires it to be non-decreasing.
Types who think \(\omega_1\) is more likely want experiments with higher \(q\), which deliver sharper evidence about the state they consider less likely.
There is a second, less familiar restriction.
Because information is worthless to types \(\theta \in \{0, 1\}\), applying the envelope theorem separately on \([0, \theta^*]\) and \([\theta^*, 1]\) and matching the two expressions for the rent of the pivotal type \(\theta^*\) forces
Note that this integral is taken with respect to \(d\theta\), not \(dF(\theta)\).
With those two constraints, the seller’s problem reduces to
subject to \(q\) non-decreasing and (36.14).
36.7.1. Solving it as a linear program#
The integrand of (36.15) is concave and piecewise linear in \(q\), since \(\min\{(d - q) f, 0\} = -f \max\{q - d, 0\}\) with \(d = u_1 - u_2\) and \(f \geq 0\).
Maximizing a concave piecewise-linear objective subject to linear constraints is a linear program.
Introducing \(z(\theta) \geq \max\{q(\theta) - d,\ 0\}\) and discretizing \(\theta\) on a grid gives
subject to \(z_n \geq q_n - d\), \(z_n \geq 0\), \(q_{n+1} \geq q_n\), \(-u_2 \leq q_n \leq u_1\), and \(\sum_n w_n q_n = d\).
def solve_menu(theta, f, u1=1.0, u2=1.0):
    """Solve the seller's problem on a grid of types by linear programming."""
    N = len(theta)
    dth = theta[1] - theta[0]
    f = f / (np.sum(f) * dth)                               # density on the grid
    F = np.cumsum(f) * dth
    w = np.full(N, dth)
    d = u1 - u2

    c = np.concatenate([-(theta * f + F) * w, f * w])       # linprog minimizes
    A_ub = np.hstack([np.eye(N), -np.eye(N)])               # q - z <= d
    b_ub = np.full(N, d)
    D = np.zeros((N - 1, 2 * N))                            # q_n - q_{n+1} <= 0
    rows = np.arange(N - 1)
    D[rows, rows], D[rows, rows + 1] = 1.0, -1.0
    A_ub = np.vstack([A_ub, D])
    b_ub = np.concatenate([b_ub, np.zeros(N - 1)])
    A_eq = np.concatenate([w, np.zeros(N)])[None, :]        # integral constraint
    bounds = [(-u2, u1)] * N + [(0, None)] * N

    res = linprog(c, A_ub=A_ub, b_ub=b_ub, A_eq=A_eq, b_eq=np.array([d]),
                  bounds=bounds, method='highs')
    return res.x[:N], res
The linear program handles the monotonicity constraint automatically.
This matters, because the alternative is to implement Myerson’s ironing procedure by hand: form the virtual values
replace them by the derivatives of the convex hulls of their integrals, and then find the multiplier on (36.14) (see Myerson [1981] and Toikka [2011]).
Denote the ironed virtual values by \(\bar\phi^-\) and \(\bar\phi^+\).
Bergemann et al. [2018] show that a menu \(q^*\) is optimal if and only if it satisfies (36.14), it is constant on every interval where the relevant ironed virtual value is constant, and for some multiplier \(\lambda^* > 0\) and every \(\theta\), \(q^*(\theta)\) maximizes
over \(q \in [-u_2, u_1]\).
Where \(\bar\phi^+(\theta) \leq \bar\phi^-(\theta)\), the maximizer is \(q^* = -u_2\) if \(\bar\phi^-(\theta) < \lambda^*\), \(q^* = d\) if \(\bar\phi^+(\theta) < \lambda^* < \bar\phi^-(\theta)\), and \(q^* = u_1\) if \(\bar\phi^+(\theta) > \lambda^*\).
The linear program does all of that implicitly.
The multiplier \(\lambda^*\) on (36.14) is the dual value of the equality
constraint, -res.eqlin.marginals[0]; the sign flips because linprog minimizes minus
revenue.
We also want the prices, which follow from the requirement that a buyer at the boundary between two items be indifferent between them.
def menu_items(theta, q, u1=1.0, u2=1.0, tol=1e-4, min_width=0.01):
    """Distinct items in the menu, with the interval of types served and the price.

    Values of q taken on a negligible set of types are transition artifacts of the
    grid, not items on the menu, so we drop them.
    """
    qr = np.round(q / tol) * tol
    vals = [v for v in np.unique(qr)
            if theta[qr == v].max() - theta[qr == v].min() >= min_width]
    items = sorted([(v, theta[qr == v].min(), theta[qr == v].max()) for v in vals],
                   key=lambda x: x[1])
    out, prev_v, prev_t = [], None, 0.0
    for v, lo, hi in items:
        if value_q(v, theta, u1, u2).max() < 1e-9:      # uninformative item
            price = 0.0
        elif prev_v is None:
            price = 0.0
        else:
            price = float(value_q(v, lo, u1, u2)
                          - value_q(prev_v, lo, u1, u2) + prev_t)
        out.append((v, lo, hi, price))
        prev_v, prev_t = v, price
    return out
36.7.2. Uniformly distributed types#
With \(u_1 = u_2 = 1\) and \(\theta\) uniform, the virtual values are \(\phi^-(\theta) = 2\theta\) and \(\phi^+(\theta) = 2\theta - 1\).
Both are strictly increasing, so no ironing is required and the optimal menu should contain a single informative item.
N = 2001
theta_g = np.linspace(0, 1, N)
q_unif, res = solve_menu(theta_g, np.ones(N))

print('LP status:', res.message)
print('distinct values of q:', np.unique(np.round(q_unif, 4)))
for v, lo, hi, p in menu_items(theta_g, q_unif):
    p1, p2 = q_to_experiment(v)
    print(f'   q = {v:+.4f}  (pi1, pi2) = ({p1:.3f}, {p2:.3f})'
          f'   types [{lo:.3f}, {hi:.3f}]   price {p:.4f}')
LP status: Optimization terminated successfully. (HiGHS Status 7: Optimal)
distinct values of q: [-1. -0.  1.]
   q = -1.0000  (pi1, pi2) = (0.000, 1.000)   types [0.000, 0.249]   price 0.0000
   q = -0.0000  (pi1, pi2) = (1.000, 1.000)   types [0.250, 0.750]   price 0.2500
   q = +1.0000  (pi1, pi2) = (1.000, 0.000)   types [0.751, 1.000]   price 0.0000
The seller offers the fully informative experiment to the middle range of types at a single price and nothing to anyone else.
The cutoffs and the price match the analytic solution of Bergemann et al. [2018] exactly: full information to \(\theta \in [1/4, 3/4]\) at a price of \(1/4\).
This is the “no-haggling” outcome of Riley and Zeckhauser [1983] adapted to information.
fig, axes = plt.subplots(1, 2, figsize=(12, 4))
axes[0].plot(theta_g, 2 * theta_g, lw=2, label=r'$\phi^-(\theta) = 2\theta$')
axes[0].plot(theta_g, 2 * theta_g - 1, lw=2, label=r'$\phi^+(\theta) = 2\theta - 1$')
axes[0].axhline(0.5, color='0.4', ls='--', lw=1, label=r'$\lambda^* = 1/2$')
axes[0].set(xlabel=r'$\theta$', title='virtual values, both strictly increasing')
axes[0].legend(fontsize=9)

axes[1].step(theta_g, q_unif, lw=2, where='mid')
axes[1].set(xlabel=r'$\theta$', ylabel=r'$q^*(\theta)$', ylim=(-1.15, 1.15),
            title='optimal menu: one informative item')
axes[1].annotate('no information', (0.06, -0.85), fontsize=9)
axes[1].annotate('full information', (0.38, 0.12), fontsize=9)
axes[1].annotate('no information', (0.78, 0.85), fontsize=9)
fig.tight_layout()
plt.show()

Fig. 36.4 Optimal menu with uniformly distributed types#
36.7.3. Bimodal types and the case for versioning#
Corollary 1 of Bergemann et al. [2018] says that a second experiment is offered only when the virtual values require ironing.
Differentiating (36.16) gives
So \(\phi^-\) is increasing if and only if \(\theta^2 f(\theta)\) is increasing, and \(\phi^+\) is increasing if and only if \((1-\theta)^2 f(\theta)\) is decreasing.
Regularity fails where the density falls faster than \(\theta^{-2}\) or rises faster than \((1-\theta)^{-2}\), that is, where the density is steep.
Bergemann et al. [2018] remark informally that ironing becomes necessary when most buyers are well informed ex ante, with most types close to \(0\) or \(1\).
That remark needs qualification.
For a \(\text{Beta}(a, b)\) density both virtual values are increasing if and only if \(a \leq 1\) and \(b \leq 1\) (Exercise 36.4), so U-shaped Beta populations of well-informed buyers are regular and are offered a single item.
Steep clusters of beliefs are irregular whether they sit near the ends of \([0, 1]\) or in its interior, and Exercise 36.4 exhibits a well-informed population of that kind that is offered two items.
Irregularity is necessary for a second item but not sufficient.
\(\text{Beta}(30, 30)\) is irregular, but it is symmetric about \(1/2\), and with \(u_1 = u_2\) Corollary 1 of Bergemann et al. [2018] then delivers a single item.
We follow the paper and take an equal mixture of \(\text{Beta}(8, 30)\) and \(\text{Beta}(60, 30)\).
Each component concentrates beliefs in a narrow range, so the mixture has two steep clusters, near \(\theta \approx 0.2\) and \(\theta \approx 0.67\).
f_bimodal = (0.5 * stats.beta(8, 30).pdf(theta_g)
             + 0.5 * stats.beta(60, 30).pdf(theta_g))

def falling_intervals(theta, phi, min_width=0.01):
    """Intervals of types on which phi decreases."""
    down = np.concatenate([[0], (np.diff(phi) < 0).astype(int), [0]])
    edges = np.flatnonzero(np.diff(down))
    return [(theta[a], theta[b]) for a, b in zip(edges[::2], edges[1::2])
            if theta[b] - theta[a] >= min_width]


dth = theta_g[1] - theta_g[0]
F_bi = np.cumsum(f_bimodal) * dth
for name, phi in [('phi-', theta_g * f_bimodal + F_bi),
                  ('phi+', (theta_g - 1) * f_bimodal + F_bi)]:
    print(f'{name} decreases on',
          ', '.join(f'[{a:.3f}, {b:.3f}]'
                    for a, b in falling_intervals(theta_g, phi)))

q_bi, res_bi = solve_menu(theta_g, f_bimodal)

print('\nLP status:', res_bi.message)
print('distinct values of q:', np.unique(np.round(q_bi, 3)))
print(f'multiplier lambda* = {-res_bi.eqlin.marginals[0]:.4f}')
print()
for v, lo, hi, p in menu_items(theta_g, q_bi):
    p1, p2 = q_to_experiment(v)
    label = 'no information' if abs(p) < 1e-9 else (
        'full information' if abs(v) < 1e-6 else 'partial information')
    print(f'   q = {v:+.4f}  (pi1, pi2) = ({p1:.3f}, {p2:.3f})'
          f'   types [{lo:.3f}, {hi:.3f}]   price {p:.4f}   {label}')
phi- decreases on [0.237, 0.472], [0.678, 0.955]
phi+ decreases on [0.000, 0.184], [0.475, 0.655]

LP status: Optimization terminated successfully. (HiGHS Status 7: Optimal)
distinct values of q: [-1.    -0.214 -0.     1.   ]
multiplier lambda* = 0.6684

   q = -1.0000  (pi1, pi2) = (0.000, 1.000)   types [0.000, 0.175]   price 0.0000   no information
   q = -0.2141  (pi1, pi2) = (0.786, 1.000)   types [0.175, 0.550]   price 0.1375   partial information
   q = -0.0000  (pi1, pi2) = (1.000, 1.000)   types [0.551, 0.745]   price 0.2555   full information
   q = +1.0000  (pi1, pi2) = (1.000, 0.000)   types [0.745, 1.000]   price 0.0000   no information
\(\phi^-\) decreases on the upper flank of each cluster, where the density falls steeply; \(\phi^+\) decreases on the lower flank of each cluster, where it rises steeply.
Both virtual values require ironing.
Now the menu contains two informative items, in line with Proposition 36.1 and with the result of Bergemann et al. [2018] that some optimal menu contains at most two.
The partial item has \(\pi_2 = 1\), so signal \(s_1\) occurs only in state \(\omega_1\) and perfectly reveals it, while signal \(s_2\) leaves the buyer uncertain.
Types \(\theta \in [0.175, 0.550]\) buy it.
That interval contains \(\theta^* = 1/2\), the type least sure what to do, who values information most.
The type indifferent between the two informative items is \(\theta \approx 0.55\).
Selling \(\overline{E}\) to \(\theta^*\) would require a further distortion of the partial item and a lower price for it, and that would cost revenue from the many types near \(\theta \approx 0.2\).
The partial item lets the seller charge a high price for \(\overline{E}\) to the large mass of buyers near \(\theta \approx 0.7\).
items = menu_items(theta_g, q_bi)

fig, axes = plt.subplots(1, 2, figsize=(12, 4))
axes[0].plot(theta_g, f_bimodal, lw=2, color='C2')
axes[0].fill_between(theta_g, f_bimodal, alpha=0.2, color='C2')
axes[0].set(xlabel=r'$\theta$', ylabel='density',
            title='beliefs packed into two steep clusters')

axes[1].step(theta_g, q_bi, lw=2, where='mid')
axes[1].set(xlabel=r'$\theta$', ylabel=r'$q^*(\theta)$', ylim=(-1.15, 1.15),
            title='optimal menu: two informative items')
for v, lo, hi, p in items:
    if p > 1e-9:
        axes[1].annotate(f'price {p:.3f}', ((lo + hi) / 2, v + 0.12),
                         ha='center', fontsize=9)
fig.tight_layout()
plt.show()
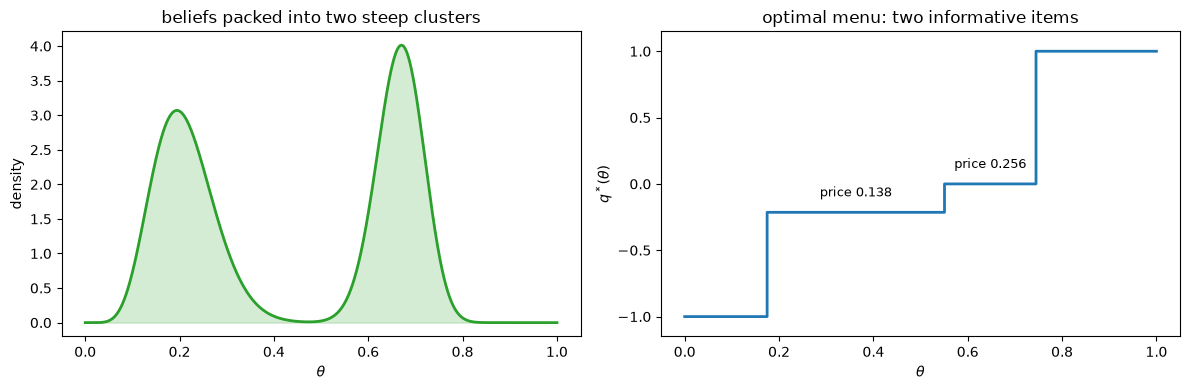
Fig. 36.5 Bimodal type density and the resulting two-item menu#
We can see directly why the seller bothers.
Every type values \(\overline{E}\) at least as much as any other experiment, so the best single-item menu sells \(\overline{E}\) at a posted price \(p\).
With \(u_1 = u_2 = 1\), \(V(\overline{E}, \theta) = \min\{\theta, 1 - \theta\}\), so types \(\theta \in [p, 1 - p]\) buy and revenue is \(p\,[F(1 - p) - F(p)]\).
def revenue(theta, q, f, u1=1.0, u2=1.0):
    """Expected revenue from the menu q under density f."""
    dth = theta[1] - theta[0]
    price = np.zeros_like(theta)
    for v, lo, hi, p in menu_items(theta, q, u1, u2):
        price[(theta >= lo) & (theta <= hi)] = p
    return np.sum(price * f) * dth / (np.sum(f) * dth)


def F_mix(x):
    """Distribution function of the bimodal mixture."""
    return 0.5 * stats.beta(8, 30).cdf(x) + 0.5 * stats.beta(60, 30).cdf(x)


p_post = np.linspace(0, 0.5, 5001)
rev_post = p_post * (F_mix(1 - p_post) - F_mix(p_post))
k = rev_post.argmax()
rev_two = revenue(theta_g, q_bi, f_bimodal)

print(f'revenue, optimal two-item menu      {rev_two:.4f}')
print(f'revenue, best posted price for E_bar {rev_post[k]:.4f}'
      f'   at p = {p_post[k]:.3f}')
print(f'gain from versioning                {100 * (rev_two / rev_post[k] - 1):.1f}%')
revenue, optimal two-item menu      0.1675
revenue, best posted price for E_bar 0.1547   at p = 0.223
gain from versioning                8.3%
Adding the partial item raises revenue by about 8 percent over the best posted price for full information.
The partial experiment is not a noisier version of the same product; it is a differently positioned one, cheap enough for the well-informed types and useless enough to the ill-informed ones that it does not undercut the high price.
36.8. Concluding remarks#
Blackwell’s theorem tells us when all decision makers agree that one experiment beats another.
Read as a design principle, its real content is the size of the set where it is silent.
Bergemann et al. [2018] show that a monopolist selling data lives in that set, since screening by belief requires products that different types rank differently.
Two lessons carry beyond the model.
First, optimal degradation of information is structured rather than random: every experiment on the menu has a signal that perfectly reveals one state.
Bergemann et al. [2018] conclude that no product on an optimal menu should add unbiased noise to the seller’s data, unless buyers compete with each other downstream or the data must be anonymized.
Second, versioning requires virtual values that must be ironed, and steep densities of beliefs produce them.
How well informed the buyers are does not settle the matter: a U-shaped Beta population of well-informed buyers is offered a single item, while steep clusters of beliefs, near the ends of \([0, 1]\) or in its interior, can be offered two.
Selling information to imperfectly informed buyers has a long history.
Admati and Pfleiderer [1986] study a seller facing a continuum of ex ante identical traders who then trade a common-value asset, and find that the seller wants to supply noisy and idiosyncratic information, so that each trader retains a local monopoly on what he knows.
Their traders compete downstream, so the first lesson does not apply to them.
The heterogeneity there is created by the seller; here it is the buyer’s own prior information, and that is what turns the problem into one of screening.
Bergemann and Bonatti [2015] study a single data provider who sets a price per “cookie”, a record on an individual consumer, and an advertiser with no private information who chooses which cookies to buy.
A useful contrast is Kamenica and Gentzkow [2011], where a sender also commits to an information structure but has no monetary transfers and cares directly about the receiver’s action; here the seller cares only about revenue and cannot condition payments on the state, the signal, or the buyer’s action.
Readers who want the statistical background can return to Blackwell’s Theorem on Comparing Experiments for the equivalence between the economic, sufficiency, and uncertainty-reduction criteria, to Likelihood Ratio Processes and Bayesian Learning for how private signals generate the interim beliefs that are the buyer types here, and to Information and Market Equilibrium for what happens when information is transmitted by prices rather than sold directly.
36.9. Exercises#
Exercise 36.1
This exercise studies the congruent case, in which both types would take the same action without extra information.
Set \(u_1 = u_2 = 1\), \(\theta^L = 0.9\) and \(\theta^H = 0.7\), so that \(\theta^* = 1/2 < \theta^H < \theta^L\).
Because both types would choose \(a_1\) on their own, the seller has no reason to degrade what the low type learns about \(\omega_1\), so set \(\pi_1 = 1\) and treat \(\pi_2\) as the only choice variable.
Plot the seller’s revenue against \(\pi_2 \in [0, 1]\) for several values of \(\gamma\), and confirm that it is linear.
Conclude that the optimum is always at an endpoint, so the low type receives either full information or none.
Bergemann et al. [2018] show that the low type receives the fully informative experiment if and only if \(\gamma \leq (1 - \theta^L)/(1 - \theta^H)\).
Locate the switch point numerically by bisection and compare.
Why is the answer extremal here, when the noncongruent case in the lecture produced an interior \(\pi_1 = 4/5\)?
Solution
Here is one solution:
tL_c, tH_c = 0.9, 0.7
p2_grid = np.linspace(0, 1, 401)

fig, ax = plt.subplots()
for gamma in [0.1, 0.25, 1/3, 0.5, 0.7]:
    r = np.array([two_type_revenue(1.0, p2, tL_c, tH_c, gamma) for p2 in p2_grid])
    dev = np.abs(r - np.interp(p2_grid, [0, 1], [r[0], r[-1]])).max()
    ax.plot(p2_grid, r, lw=2, label=rf'$\gamma = {gamma:.3f}$')
    print(f'gamma = {gamma:.3f}:  revenue at pi2=0 is {r[0]:.5f}, '
          f'at pi2=1 is {r[-1]:.5f},  deviation from linear {dev:.1e}')
ax.set(xlabel=r'$\pi_2$', ylabel='revenue',
       title='revenue is linear in $\pi_2$, so the optimum is at an endpoint')
ax.legend(fontsize=9)
fig.tight_layout()
plt.show()
gamma = 0.100:  revenue at pi2=0 is 0.03000, at pi2=1 is 0.10000,  deviation from linear 8.3e-17
gamma = 0.250:  revenue at pi2=0 is 0.07500, at pi2=1 is 0.10000,  deviation from linear 8.3e-17
gamma = 0.333:  revenue at pi2=0 is 0.10000, at pi2=1 is 0.10000,  deviation from linear 9.7e-17
gamma = 0.500:  revenue at pi2=0 is 0.15000, at pi2=1 is 0.10000,  deviation from linear 9.7e-17
gamma = 0.700:  revenue at pi2=0 is 0.21000, at pi2=1 is 0.10000,  deviation from linear 1.1e-16

lo, hi = 0.0, 1.0
for _ in range(60):
    mid = (lo + hi) / 2
    if two_type_revenue(1, 1, tL_c, tH_c, mid) >= two_type_revenue(1, 0, tL_c, tH_c, mid):
        lo = mid
    else:
        hi = mid

print(f'numerical switch point            gamma = {lo:.6f}')
print(f'(1 - theta_L) / (1 - theta_H)           = {(1 - tL_c) / (1 - tH_c):.6f}')
numerical switch point            gamma = 0.333333
(1 - theta_L) / (1 - theta_H)           = 0.333333
Revenue is linear in \(\pi_2\) to machine precision, so the optimum is always at \(\pi_2 \in \{0, 1\}\), and the switch occurs exactly at \(\gamma = 1/3\) as predicted.
The reason for the extremal answer is that with congruent beliefs both types would choose \(a_1\) anyway, so the only question is how much the seller reveals about \(\omega_2\).
Both types then value the experiment through the same term \((1 - \theta)\pi_2 u_2\), which is why the objective and constraints are linear in the single variable \(\pi_2\) and why the no-haggling logic of Riley and Zeckhauser [1983] applies.
With noncongruent beliefs the two types take different actions on their own, the kink in the value function lies between them, and the seller can position an experiment so that it is worth much to one type and little to the other.
That possibility is what makes an interior distortion optimal.
Exercise 36.2
Corollary 1 of Bergemann et al. [2018] states that the optimal menu contains a single item whenever both virtual values (36.16) are strictly increasing, and that for uniformly distributed types this holds irrespective of the payoffs \((u_1, u_2)\).
Verify this by solving the seller’s problem with uniform types for several asymmetric payoff pairs, for instance \((u_1, u_2) \in \{(1, 1), (2, 1), (1, 3), (5, 1)\}\).
For each case report \(\theta^*\), the interval of types served, and the price.
Confirm that the fully informative experiment is always the item offered, as Proposition 36.1 requires.
Use (36.17) and (36.14) to show analytically that the multiplier is \(\lambda^* = \theta^*\), that types \(\theta \in [\theta^*/2,\ (1 + \theta^*)/2]\) are served, and that the price is \(u_1 u_2 / \bigl(2 (u_1 + u_2)\bigr)\).
Print these values next to the ones from the linear program.
Solution
Here is one solution:
print(f'{"u1":>3s}{"u2":>3s}{"theta*":>8s}{"q":>6s}{"":3s}'
      f'{"served (LP)":<16s}{"served (theory)":<17s}'
      f'{"price":>7s}{"theory":>8s}{"lambda*":>9s}{"theory":>8s}')
for u1_, u2_ in [(1, 1), (2, 1), (1, 3), (5, 1)]:
    q_a, res_a = solve_menu(theta_g, np.ones(N), u1_, u2_)
    star = u2_ / (u1_ + u2_)
    served = [it for it in menu_items(theta_g, q_a, u1_, u2_) if it[3] > 1e-9]
    assert len(served) == 1                     # a single informative item
    v, lo, hi, p = served[0]
    assert abs(v - (u1_ - u2_)) < 1e-3          # the item is fully informative
    lam = -res_a.eqlin.marginals[0]
    print(f'{u1_:3d}{u2_:3d}{star:8.4f}{v:6.1f}{"":3s}'
          f'{f"[{lo:.3f}, {hi:.3f}]":<16s}'
          f'{f"[{star / 2:.3f}, {(1 + star) / 2:.3f}]":<17s}'
          f'{p:7.4f}{u1_ * u2_ / (2 * (u1_ + u2_)):8.4f}'
          f'{lam:9.4f}{star:8.4f}')
print('\nevery menu contains exactly one informative item, '
      'and it is the fully informative one')
 u1 u2  theta*     q   served (LP)     served (theory)    price  theory  lambda*  theory
  1  1  0.5000  -0.0   [0.250, 0.750]  [0.250, 0.750]    0.2500  0.2500   0.5002  0.5000
  2  1  0.3333   1.0   [0.167, 0.666]  [0.167, 0.667]    0.3340  0.3333   0.3343  0.3333
  1  3  0.7500  -2.0   [0.375, 0.875]  [0.375, 0.875]    0.3750  0.3750   0.7501  0.7500
  5  1  0.1667   4.0   [0.084, 0.584]  [0.083, 0.583]    0.4200  0.4167   0.1674  0.1667

every menu contains exactly one informative item, and it is the fully informative one
The virtual values for a uniform density are \(\phi^-(\theta) = 2\theta\) and \(\phi^+(\theta) = 2\theta - 1\) whatever the payoffs, because \(u_1\) and \(u_2\) enter the seller’s problem only through \(d = u_1 - u_2\) and the bounds on \(q\), not through \(f\) or \(F\).
Both are strictly increasing, so no ironing is needed and a single item is optimal.
The payoffs do move \(\theta^*\) and hence which types are served and at what price, but they never make versioning worthwhile under a uniform density.
For the analytic benchmark, no ironing is needed, so (36.17) gives \(q^* = -u_2\) for \(\theta < \lambda^*/2\), \(q^* = u_1 - u_2\) for \(\lambda^*/2 < \theta < (1 + \lambda^*)/2\), and \(q^* = u_1\) for \(\theta > (1 + \lambda^*)/2\).
Substituting into (36.14) gives
so \(\lambda^* (u_1 + u_2) = u_2\) and \(\lambda^* = \theta^*\).
The lowest type served, \(\theta^*/2\), is indifferent between \(\overline{E}\) and nothing.
For \(\theta \leq \theta^*\) we have \(V(\overline{E}, \theta) = \theta u_1\), so the price is \(u_1 \theta^* / 2 = u_1 u_2 / \bigl(2(u_1 + u_2)\bigr)\).
The highest type served, \((1 + \theta^*)/2\), values \(\overline{E}\) at \((1 - \theta) u_2 = u_1 u_2 / \bigl(2(u_1 + u_2)\bigr)\), the same price.
The linear program matches all three objects up to the discretization of the type grid.
Exercise 36.3
This exercise connects the lecture back to Blackwell’s Theorem on Comparing Experiments.
Blackwell’s theorem says that if \(E'\) is a garbling of \(E\) then every decision maker weakly prefers \(E\).
Draw many random pairs of binary experiments with \(\pi_1 + \pi_2 \geq 1\).
For each pair, use
garblingto decide whether one is a garbling of the other, and separately compute whether one dominates the other in value at every type.Because \(V(E, \theta)\) is piecewise linear in \(\theta\), it suffices to compare the two values at \(\theta \in \{0, 1\}\) and at the types where either value function has a kink.
Confirm that garbling implies unanimous preference, and report what fraction of random pairs Blackwell’s order fails to rank.
Among the unranked pairs, verify that some types prefer one experiment and some the other.
Explain why, for two-state experiments, the pairs that Blackwell’s order leaves unranked should be exactly the pairs on which types disagree.
What goes wrong if dominance is checked only on a finite grid of types?
Solution
Here is one solution:
def kinks(pi1, pi2, u1=1.0, u2=1.0):
    """Endpoints and types at which V(E, theta) can change slope."""
    k = [0.0, 1.0, u2 / (u1 + u2)]
    for a, b in [(pi1 * u1, (1 - pi2) * u2), ((1 - pi1) * u1, pi2 * u2)]:
        if a + b > 0:
            k.append(b / (a + b))       # indifference after one of the signals
    return np.array(k)


rng = np.random.default_rng(0)
grid_t = np.linspace(0.001, 0.999, 999)

n_pairs, n_garble, n_unranked, violations = 4000, 0, 0, 0
n_disagree, n_disagree_grid, n_unanimous_unranked = 0, 0, 0
for _ in range(n_pairs):
    (a1, a2), (b1, b2) = rng.uniform(0, 1, 2), rng.uniform(0, 1, 2)
    if a1 + a2 < 1 or b1 + b2 < 1:
        continue
    Ea, Eb = experiment(a1, a2), experiment(b1, b2)
    t = np.concatenate([kinks(a1, a2), kinks(b1, b2)])
    va, vb = value(a1, a2, t), value(b1, b2, t)
    va_g, vb_g = value(a1, a2, grid_t), value(b1, b2, grid_t)

    a_garbles_b = garbling(Ea, Eb) is not None      # Eb is a garbling of Ea
    b_garbles_a = garbling(Eb, Ea) is not None
    a_dominates = np.all(va >= vb - 1e-12)
    b_dominates = np.all(vb >= va - 1e-12)

    if a_garbles_b:
        n_garble += 1
        if not a_dominates:
            violations += 1
    if b_garbles_a:
        n_garble += 1
        if not b_dominates:
            violations += 1
    if not (a_garbles_b or b_garbles_a):
        n_unranked += 1
        if not (a_dominates or b_dominates):
            n_disagree += 1
        if not (np.all(va_g >= vb_g - 1e-9) or np.all(vb_g >= va_g - 1e-9)):
            n_disagree_grid += 1
    if (a_dominates and not a_garbles_b) or (b_dominates and not b_garbles_a):
        n_unanimous_unranked += 1

print(f'garbling relations found              {n_garble}')
print(f'violations of Blackwell               {violations}')
print(f'unanimous rankings without garbling   {n_unanimous_unranked}')
print(f'pairs unranked by Blackwell           {n_unranked}')
print(f'  of which types disagree (kinks)     {n_disagree}')
print(f'  of which types disagree (grid)      {n_disagree_grid}')
garbling relations found              674
violations of Blackwell               0
unanimous rankings without garbling   0
pairs unranked by Blackwell           318
  of which types disagree (kinks)     318
  of which types disagree (grid)      317
Blackwell’s theorem is never violated: whenever one experiment garbles into the other, every type prefers the garbling source.
The converse also holds in every draw: whenever all types rank two experiments the same way, one is a garbling of the other.
A large share of random pairs is left unranked, and for every one of them some types prefer one experiment and some the other.
That unranked region is exactly the room the data seller needs.
If Blackwell’s order were complete, every buyer would agree on the ranking of all information products, the seller’s problem would collapse to standard nonlinear pricing over a single quality index, and the horizontal screening described in this lecture would be impossible.
The match between garbling and unanimous preference is exact for two-state experiments.
Fix a reference prior \(c \in (0, 1)\) and let \(x\) denote the posterior probability of \(\omega_1\) that a signal induces under \(c\).
The gross value of \(E\) to type \(\theta\) with \(u_1 = u_2 = 1\) equals the expectation, under \(c\), of the convex function \(k_\theta(x) = \max\{\theta x / c,\ (1 - \theta)(1 - x)/(1 - c)\}\), which has a single kink.
As \(\theta\) ranges over \((0, 1)\), the kink ranges over \((0, 1)\).
Every convex function on \([0, 1]\) is an affine function plus a nonnegative mixture of such one-kink functions, and the affine part has the same expectation under every experiment.
By Theorem 30.2, \(E'\) is a garbling of \(E\) if and only if \(V(E, \theta) \geq V(E', \theta)\) for every \(\theta\).
A check on a finite grid of types can miss a disagreement confined to a short interval between grid points.
The grid of 999 types does so once in the draws above.
Evaluating at kinks is exact, because the difference of two piecewise-linear functions attains its maximum and minimum at kinks or endpoints.
Exercise 36.4
This exercise characterizes the type densities for which the virtual values (36.16) need no ironing.
Use (36.18) to show that on \((0, 1)\), \(\phi^-\) is strictly increasing if and only if \(\theta^2 f(\theta)\) is strictly increasing, and \(\phi^+\) is strictly increasing if and only if \((1 - \theta)^2 f(\theta)\) is strictly decreasing.
Deduce that for a \(\text{Beta}(a, b)\) density both virtual values are strictly increasing if and only if \(a \leq 1\) and \(b \leq 1\).
Confirm the condition numerically on a grid of \((a, b)\) pairs.
Use
solve_menuto show that the U-shaped densities \(\text{Beta}(0.5, 0.5)\), \(\text{Beta}(0.3, 0.3)\) and \(\text{Beta}(0.5, 0.8)\) are offered a single item, that the irregular \(\text{Beta}(30, 30)\) is also offered a single item, and that the irregular \(\text{Beta}(60, 30)\) is offered two informative items.Show that an equal mixture of \(\text{Beta}(2, 60)\) and \(\text{Beta}(40, 4)\), a population in which most buyers are well informed, is irregular and is offered two informative items.
Solution
Here is one solution.
For \(\theta \in (0, 1)\),
So \(\phi^{-\prime}\) has the sign of the derivative of \(\theta^2 f\), and \(\phi^{+\prime}\) has the sign opposite to the derivative of \((1-\theta)^2 f\).
For \(f(\theta) \propto \theta^{a-1}(1 - \theta)^{b-1}\),
The first expression is positive on all of \((0, 1)\) if and only if \(b \leq 1\), since for \(b > 1\) it diverges to \(-\infty\) as \(\theta \to 1\).
The second is negative on all of \((0, 1)\) if and only if \(a \leq 1\), since for \(a > 1\) it diverges to \(+\infty\) as \(\theta \to 0\).
th_in = theta_g[1:-1]                   # Beta densities can be infinite at 0 and 1


def mixture(components):
    """Density and distribution function of an equal mixture of Beta laws."""
    f_c = np.mean([stats.beta(a, b).pdf(th_in) for a, b in components], axis=0)
    F_c = np.mean([stats.beta(a, b).cdf(th_in) for a, b in components], axis=0)
    return f_c, F_c


def regular(f_c, F_c):
    """True if both virtual values increase on the grid."""
    return (np.all(np.diff(th_in * f_c + F_c) > 0)
            and np.all(np.diff((th_in - 1) * f_c + F_c) > 0))


ab_grid = [0.3, 0.5, 0.8, 1.0, 1.2, 2.0, 5.0]
mismatch = [(a, b) for a in ab_grid for b in ab_grid
            if regular(*mixture([(a, b)])) != (a <= 1 and b <= 1)]
print(f'(a, b) pairs checked: {len(ab_grid)**2},  mismatches: {mismatch}')

for comps in [[(0.5, 0.5)], [(0.3, 0.3)], [(0.5, 0.8)], [(30, 30)], [(60, 30)],
              [(2, 60), (40, 4)]]:
    f_c, F_c = mixture(comps)
    near_ends = np.mean([stats.beta(a, b).cdf(0.15) + stats.beta(a, b).sf(0.85)
                         for a, b in comps])
    q_c, _ = solve_menu(th_in, f_c)
    informative = [it for it in menu_items(th_in, q_c) if it[3] > 1e-9]
    print('\n' + ' + '.join(f'Beta{ab}' for ab in comps)
          + f':  regular = {regular(f_c, F_c)},'
          f'  mass within 0.15 of 0 or 1 = {near_ends:.2f},'
          f'  informative items = {len(informative)}')
    for v, lo, hi, p in informative:
        print(f'   q = {v:+.3f}   types [{lo:.3f}, {hi:.3f}]   price {p:.4f}')
(a, b) pairs checked: 49,  mismatches: []

Beta(0.5, 0.5):  regular = True,  mass within 0.15 of 0 or 1 = 0.51,  informative items = 1
   q = -0.000   types [0.237, 0.764]   price 0.2365

Beta(0.3, 0.3):  regular = True,  mass within 0.15 of 0 or 1 = 0.64,  informative items = 1
   q = -0.000   types [0.230, 0.770]   price 0.2295

Beta(0.5, 0.8):  regular = True,  mass within 0.15 of 0 or 1 = 0.46,  informative items = 1
   q = -0.000   types [0.240, 0.761]   price 0.2395

Beta(30, 30):  regular = False,  mass within 0.15 of 0 or 1 = 0.00,  informative items = 1
   q = -0.000   types [0.384, 0.617]   price 0.3835

Beta(60, 30):  regular = False,  mass within 0.15 of 0 or 1 = 0.00,  informative items = 2
   q = -0.821   types [0.164, 0.289]   price 0.0294
   q = -0.000   types [0.289, 0.733]   price 0.2670

Beta(2, 60) + Beta(40, 4):  regular = False,  mass within 0.15 of 0 or 1 = 0.95,  informative items = 2
   q = -0.058   types [0.027, 0.719]   price 0.0254
   q = -0.000   types [0.719, 0.933]   price 0.0670
The numerical check agrees with the condition \(a \leq 1\), \(b \leq 1\) at every pair.
The three U-shaped densities are regular and are offered only \(\overline{E}\).
\(\text{Beta}(30, 30)\) is irregular but symmetric about \(\theta^* = 1/2\), and it is also offered only \(\overline{E}\).
The steep, asymmetric \(\text{Beta}(60, 30)\) is offered a partial item with \(q < 0\) as well as \(\overline{E}\).
The mixture of \(\text{Beta}(2, 60)\) and \(\text{Beta}(40, 4)\) puts more of its mass within \(0.15\) of \(0\) or \(1\) than any of the U-shaped densities.
Its two clusters are steep, it is irregular, and it is offered two informative items.
Both kinds of population consist mostly of well-informed buyers; the steepness of the density separates them.
Exercise 36.5
This exercise irons the virtual values of the bimodal example by hand and checks the menu that the linear program found.
Set \(u_1 = u_2 = 1\), so that \(d = 0\), and use the density f_bimodal.
Compute \(\Phi^\pm(\theta) = \int_0^\theta \phi^\pm(x)\, dx\) on the grid, their greatest convex minorants, and the ironed virtual values \(\bar\phi^\pm\) as the slopes of the minorants.
By (36.17), types with \(\bar\phi^- < \lambda^*\) get \(q = -1\), types with \(\bar\phi^+ < \lambda^* < \bar\phi^-\) get \(q = 0\), types with \(\bar\phi^+ > \lambda^*\) get \(q = 1\), and types on an interval where \(\bar\phi^- = \lambda^*\) share a common \(q_m \in [-1, 0]\).
Find \(\lambda^*\) and \(q_m\) from the integral constraint (36.14).
Compare \(\lambda^*\), \(q_m\), the interval of types who buy the partial item, and the cutoff above which types buy nothing with the solution of the linear program.
Plot \(\phi^\pm\), \(\bar\phi^\pm\) and \(\lambda^*\).
Solution
Here is one solution.
def ironed(theta, phi):
    """Slopes of the greatest convex minorant of the integral of phi."""
    dth = theta[1] - theta[0]
    Phi = np.concatenate([[0.0], np.cumsum((phi[1:] + phi[:-1]) / 2) * dth])
    hull = [0]                                       # lower convex hull
    for i in range(1, len(theta)):
        while len(hull) >= 2:
            j, k = hull[-2], hull[-1]
            if ((Phi[k] - Phi[j]) * (theta[i] - theta[j])
                    >= (Phi[i] - Phi[j]) * (theta[k] - theta[j])):
                hull.pop()
            else:
                break
        hull.append(i)
    phi_bar = np.empty_like(phi)
    for j, k in zip(hull[:-1], hull[1:]):
        phi_bar[j:k + 1] = (Phi[k] - Phi[j]) / (theta[k] - theta[j])
    return phi_bar


dth = theta_g[1] - theta_g[0]
f_n = f_bimodal / (np.sum(f_bimodal) * dth)
F_n = np.cumsum(f_n) * dth
phi_m, phi_p = theta_g * f_n + F_n, (theta_g - 1) * f_n + F_n
bar_m, bar_p = ironed(theta_g, phi_m), ironed(theta_g, phi_p)
print('phi_bar+ <= phi_bar- everywhere:', np.all(bar_p <= bar_m + 1e-12))


def integral_q(lam):
    """Integral of q when types with bar_m = lam are assigned q = 0."""
    return (-(bar_m < lam).sum() + (bar_p > lam).sum()) * dth


lo, hi = bar_m.min(), bar_m.max()                   # integral_q decreases in lam
for _ in range(200):
    mid = (lo + hi) / 2
    lo, hi = (mid, hi) if integral_q(mid) > 0 else (lo, mid)
lam_star = hi

pooled = np.abs(bar_m - lam_star) < 1e-9
th_a, th_b = theta_g[pooled].min(), theta_g[pooled].max()
th_c = theta_g[bar_p > lam_star].min()
q_m = (th_a - (1 - th_c)) / (th_b - th_a)

lp_items = [it for it in menu_items(theta_g, q_bi) if it[3] > 1e-9]
(q_lp, a_lp, b_lp, _), (_, _, c_lp, _) = lp_items
print(f'\n{"":24s}{"by hand":>10s}{"LP":>10s}')
print(f'{"multiplier lambda*":24s}{lam_star:10.4f}{-res_bi.eqlin.marginals[0]:10.4f}')
print(f'{"partial item q_m":24s}{q_m:10.4f}{q_lp:10.4f}')
print(f'{"lowest buyer":24s}{th_a:10.4f}{a_lp:10.4f}')
print(f'{"partial / full cutoff":24s}{th_b:10.4f}{b_lp:10.4f}')
print(f'{"highest buyer":24s}{th_c:10.4f}{c_lp:10.4f}')
phi_bar+ <= phi_bar- everywhere: True

                           by hand        LP
multiplier lambda*          0.6684    0.6684
partial item q_m           -0.2141   -0.2141
lowest buyer                0.1745    0.1750
partial / full cutoff       0.5505    0.5505
highest buyer               0.7450    0.7445
fig, ax = plt.subplots()
ax.plot(theta_g, phi_m, lw=1, color='C0', alpha=0.5, label=r'$\phi^-$')
ax.plot(theta_g, bar_m, lw=2, color='C0', label=r'$\bar\phi^-$')
ax.plot(theta_g, phi_p, lw=1, color='C1', alpha=0.5, label=r'$\phi^+$')
ax.plot(theta_g, bar_p, lw=2, color='C1', label=r'$\bar\phi^+$')
ax.axhline(lam_star, color='0.3', ls='--', lw=1, label=r'$\lambda^*$')
ax.axvspan(th_a, th_b, color='C2', alpha=0.15, label='partial item')
ax.set(xlabel=r'$\theta$', ylim=(-4, 4),
       title='ironed virtual values for the bimodal density')
ax.legend(fontsize=9, ncol=2)
fig.tight_layout()
plt.show()
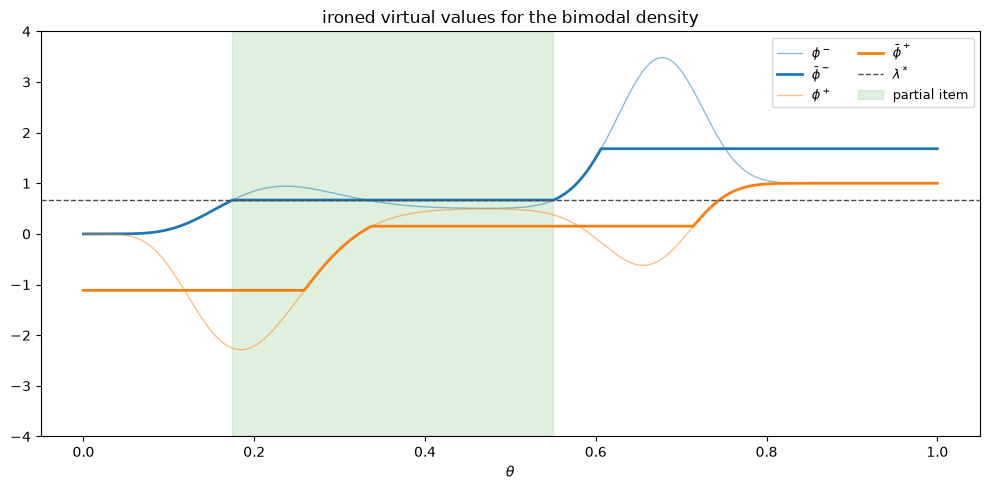
The multiplier is the level at which the integral of \(q\) jumps across zero.
Just below \(\lambda^*\) the pooled types get \(q = 0\) and the integral is positive; just above \(\lambda^*\) they get \(q = -1\) and the integral is negative.
On the pooled interval \([\theta_a, \theta_b]\) the integral constraint reads \(-\theta_a + q_m (\theta_b - \theta_a) + (1 - \theta_c) = 0\), which gives \(q_m = \bigl(\theta_a - (1 - \theta_c)\bigr) / (\theta_b - \theta_a)\).
The pooled interval is the interval on which ironing flattens \(\phi^-\) at the level \(\lambda^*\).
Its upper end, \(\theta \approx 0.55\), is the type indifferent between the partial item and \(\overline{E}\).
The hand calculation and the linear program agree up to the grid spacing.